Python有很多实用的工具,包和函数
ipython
pip install ipython
可以在终端优雅的运行
python代码
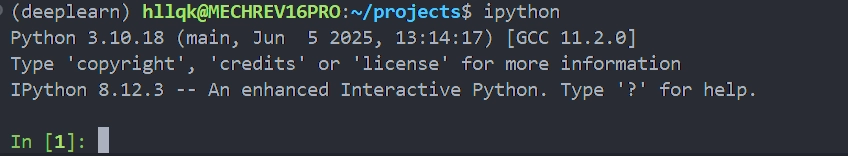
按ctrl+z退出
pprint 模块:打印 Python 对象
pprint 是 pretty printer 的缩写,用来打印 Python 数据结构,与 print 相比,它打印出来的结构更加整齐,便于阅读。import pprint
生成一个 Python 对象:
data = (
"this is a string",
[1, 2, 3, 4],
("more tuples", 1.0, 2.3, 4.5),
"this is yet another string"
)
使用普通的
print 函数:print(data)
('this is a string',
[1, 2, 3, 4],
('more tuples', 1.0, 2.3, 4.5),
'this is yet another string')
使用
pprint 模块中的 pprint 函数:pprint.pprint(data)
('this is a string', [1, 2, 3, 4], ('more tuples', 1.0, 2.3, 4.5), 'this is yet another string')
可以看到,这样打印出来的内容更加美观。
pickle, cPickle 模块:序列化 Python 对象
pickle 模块实现了一种算法,可以将任意一个 Python 对象转化为一系列的字节,也可以将这些字节重构为一个有相同特征的新对象。写入
import pickle
data=[{'name': 'Alice', 'age': 25}]
data_string=pickle.dumps(data)
with open('data.pkl', 'wb') as f:
f.write(data_string)
读取
import pickle
model=pickle.load(open('data.pkl','rb'))
print(model)
json 模块:处理 JSON 数据
SON (JavaScript Object Notation)") 是一种轻量级的数据交换格式,易于人阅读和编写,同时也易于机器解析和生成。
JSON 基础
JSON 的基础结构有两种:键值对 (name/value pairs) 和数组 (array)。JSON 具有以下形式:object- 对象,用花括号表示,形式为(数据是无序的):
{ pair_1, pair_2, ..., pair_n }
pair- 键值对,形式为:
string : value
array- 数组,用中括号表示,形式为(数据是有序的):
[value_1, value_2, ..., value_n ]
value- 值,可以是
string字符串
number数字
object对象
array数组
true / false / null特殊值
string字符串
例子:
{
"name": "echo",
"age": 24,
"coding skills": ["python", "matlab", "java", "c", "c++", "ruby", "scala"],
"ages for school": {
"primary school": 6,
"middle school": 9,
"high school": 15,
"university": 18
},
"hobby": ["sports", "reading"],
"married": false
}
JSON 与 Python 的转换
假设我们已经将上面这个
JSON 对象写入了一个字符串:import json from pprint import pprint info_string = """ { "name": "echo", "age": 24, "coding skills": ["python", "matlab", "java", "c", "c++", "ruby", "scala"], "ages for school": { "primary school": 6, "middle school": 9, "high school": 15, "university": 18 }, "hobby": ["sports", "reading"], "married": false } """
我们可以用 `json.loads()`(load string) 方法从字符串中读取
JSON 数据:info = json.loads(info_string) pprint(info)
{u'age': 24,
u'ages for school': {u'high school': 15,
u'middle school': 9,
u'primary school': 6,
u'university': 18},
u'coding skills': [u'python',
u'matlab',
u'java',
u'c',
u'c++',
u'ruby',
u'scala'],
u'hobby': [u'sports', u'reading'],
u'married': False,
u'name': u'echo'}
此时,我们将原来的
JSON 数据变成了一个 Python 对象,在我们的例子中这个对象是个字典(也可能是别的类型,比如列表):In [3]:
type(info)
Out[3]:
dict
可以使用
json.dumps() 将一个 Python 对象变成 JSON 对象:In [4]:
info_json = json.dumps(info)

print(info_json)
{"name": "echo", "age": 24, "married": false, "ages for school": {"middle school": 9, "university": 18, "high school": 15, "primary school": 6}, "coding skills": ["python", "matlab", "java", "c", "c++", "ruby", "scala"], "hobby": ["sports", "reading"]}
从中我们可以看到,生成的
JSON 字符串中,数组的元素顺序是不变的(始终是 ["python", "matlab", "java", "c", "c++", "ruby", "scala"]),而对象的元素顺序是不确定的。生成和读取 JSON 文件
与
pickle 类似,我们可以直接从文件中读取 JSON 数据,也可以将对象保存为 JSON 格式。json.dump(obj, file)将对象保存为 JSON 格式的文件
json.load(file)从 JSON 文件中读取数据
In [5]:
with open("info.json", "w") as f:
json.dump(info, f)
可以查看
info.json 的内容:In [6]:
with open("info.json") as f:
print f.read()
{"name": "echo", "age": 24, "married": false, "ages for school": {"middle school": 9, "university": 18, "high school": 15, "primary school": 6}, "coding skills": ["python", "matlab", "java", "c", "c++", "ruby", "scala"], "hobby": ["sports", "reading"]}
从文件中读取数据:
In [7]:
with open("info.json") as f:
info_from_file = json.load(f)

pprint(info_from_file)
{u'age': 24,
u'ages for school': {u'high school': 15,
u'middle school': 9,
u'primary school': 6,
u'university': 18},
u'coding skills': [u'python',
u'matlab',
u'java',
u'c',
u'c++',
u'ruby',
u'scala'],
u'hobby': [u'sports', u'reading'],
u'married': False,
u'name': u'echo'}
删除生成的文件:
In [8]:
import os
os.remove("info.json")
shutil 模块:高级文件操作
import shutil
# 快速删除一个目录及其所有内容
# shutil.rmtree('tts')
# 复制一个目录及其所有内容
# shutil.copytree('tts', 'tts_copy')
# 移动一个目录及其所有内容
# shutil.move('tts_copy', 'tts_move')
# 产生压缩文件
# shutil.make_archive("test_archive", "zip", "test_dir/")
logging
模块:记录日志
logging 模块可以用来记录日志:import logging
logging 的日志类型有以下几种:logging.critical(msg)
logging.error(msg)
logging.warning(msg)
logging.info(msg)
logging.debug(msg)
级别排序为:
CRITICAL > ERROR > WARNING > INFO > DEBUG > NOTSET默认情况下,
logging 的日志级别为 WARNING,只有不低于 WARNING 级别的日志才会显示在命令行。logging.critical('This is critical message') logging.error('This is error message') logging.warning('This is warning message') # 不会显示 logging.info('This is info message') logging.debug('This is debug message')
CRITICAL:root:This is critical message
ERROR:root:This is error message
WARNING:root:This is warning message
可以这样修改默认的日志级别:
logging.root.setLevel(level=logging.INFO)

logging.info('This is info message')
INFO:root:This is info message
可以通过
logging.basicConfig() 函数来改变默认的日志显示方式:logging.basicConfig(format='%(asctime)s: %(levelname)s: %(message)s') logger = logging.getLogger("this program") logger.critical('This is critical message')
CRITICAL:this program:This is critical message
requests 模块:HTTP for Human
In [1]:
import requests
Python 标准库中的
urllib2 模块提供了你所需要的大多数 HTTP 功能,但是它的 API 不是特别方便使用。requests 模块号称 HTTP for Human,它可以这样使用:In [2]:
r = requests.get("http://httpbin.org/get")
r = requests.post('http://httpbin.org/post', data = {'key':'value'})
r = requests.put("http://httpbin.org/put")
r = requests.delete("http://httpbin.org/delete")
r = requests.head("http://httpbin.org/get")
r = requests.options("http://httpbin.org/get")
传入 URL 参数
假如我们想访问
httpbin.org/get?key=val,我们可以使用 params 传入这些参数:In [3]:
payload = {'key1': 'value1', 'key2': 'value2'}
r = requests.get("http://httpbin.org/get", params=payload)
查看
url :In [4]:
print(r.url)
http://httpbin.org/get?key2=value2&key1=value1
读取响应内容
Requests 会自动解码来自服务器的内容。大多数 unicode 字符集都能被无缝地解码。In [5]:
r = requests.get('https://github.com/timeline.json')

print r.text
{"message":"Hello there, wayfaring stranger. If you’re reading this then you probably didn’t see our blog post a couple of years back announcing that this API would go away: http://git.io/17AROg Fear not, you should be able to get what you need from the shiny new Events API instead.","documentation_url":"https://developer.github.com/v3/activity/events/#list-public-events"}
查看文字编码:
In [6]:
r.encoding
Out[6]:
'utf-8'
每次改变文字编码,
text 的内容也随之变化:In [7]:
r.encoding = "ISO-8859-1"

r.text
Out[7]:
u'{"message":"Hello there, wayfaring stranger. If you\xe2\x80\x99re reading this then you probably didn\xe2\x80\x99t see our blog post a couple of years back announcing that this API would go away: http://git.io/17AROg Fear not, you should be able to get what you need from the shiny new Events API instead.","documentation_url":"https://developer.github.com/v3/activity/events/#list-public-events"}'
Requests 中也有一个内置的 JSON 解码器处理 JSON 数据:In [8]:
r.json()
Out[8]:
{u'documentation_url': u'https://developer.github.com/v3/activity/events/#list-public-events',
u'message': u'Hello there, wayfaring stranger. If you\xe2\x80\x99re reading this then you probably didn\xe2\x80\x99t see our blog post a couple of years back announcing that this API would go away: http://git.io/17AROg Fear not, you should be able to get what you need from the shiny new Events API instead.'}
如果
JSON 解码失败, r.json 就会抛出一个异常。响应状态码
In [9]:
r = requests.get('http://httpbin.org/get')

r.status_code
Out[9]:
407
响应头
In [10]:
r.headers['Content-Type']
Out[10]:
'text/html'
更多内容引用:README - 【布客】AI Learning
评论加载中…